InfluxDB
Mite can write live test metrics (counters, gauges, histograms) to InfluxDB v1, v2, or v3, either as part of an in-process test run or as a standalone exporter process consuming stats from the message bus.
It converts the internal stats model (Counter, Gauge, Histogram — see
mite/stats.py) into
InfluxDB line-protocol points and writes them to one or more InfluxDB instances.
Quick start
Configuration
Set INFLUXDB_VERSION to select the client (default v3), then the
matching variables below. For additional simultaneous instances, suffix
every variable with _2, _3, etc.
Version |
Required env vars |
|---|---|
v1 |
|
v2 |
|
v3 |
|
A fuller reference, including how each version maps onto the underlying client, is in Configuration reference below.
Via mite test run (in-process)
Pass --influxdb=N to attach N InfluxDBProcessor message processors
(mite/influxdb_processor.py)
alongside the existing message processors:
# Single InfluxDB instance (suffix "")
mite journey test --influxdb=1 mite.example:journey mite.example:datapool

# Two InfluxDB instances at once (suffix "" and "_2")
mite scenario test --influxdb=2 mite.example:scenario

# Include raw histogram buckets (le-tagged points) in addition to percentiles
mite scenario test --influxdb=1 --include-buckets mite.example:scenario
--include-buckets additionally emits raw histogram bucket points (le-tagged,
Prometheus-style) alongside the computed percentiles, letting downstream tools
reconstruct exact distributions instead of relying on pre-computed percentiles.
Each InfluxDBProcessor wraps its own Stats aggregator
(mite/stats.py) and
InfluxMetrics sink, so stats dumps are converted to points and flushed on the
cadence described in Layers, independent of whatever other message
processors (--message-processors) are attached.
As an individual component (influxdb_exporter)
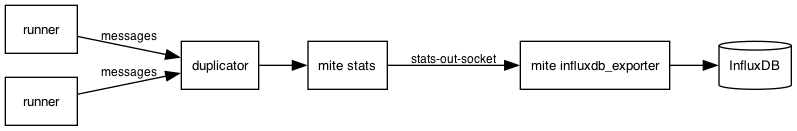
InfluxDB writing can also run completely out-of-process, decoupled from the
test itself — useful when running distributed load tests (separate
controller/runner/duplicator processes) where stats are published to a
message bus rather than consumed in-process:
mite influxdb_exporter --stats-out-socket=tcp://0.0.0.0:14305 --include-buckets
This binds a receiver to --stats-out-socket (the same socket mite stats
publishes dumped stats to), feeds every received message into a single
InfluxMetrics instance (via mite.web.influx_metrics(),
mite/web/__init__.py),
and flushes to InfluxDB on receipt — independent of any particular test process.
It reads the same INFLUXDB_*/INFLUXDB_VERSION environment variables as
above, but always the unsuffixed, single-instance config: influxdb_exporter
does not support the --influxdb=N multi-instance flag. To write to multiple
InfluxDB instances, run multiple influxdb_exporter processes, each with its
own (unsuffixed) env vars pointed at a different instance.
Seeding metrics before a run (influxdb init)
mite influxdb init --influxdb=2
Writes a zero-valued point for every registered mite_stats entry point stat
(see pyproject.toml
[project.entry-points.mite_stats]) to each configured InfluxDB instance, so
dashboards and alerts have a baseline series to chart against before the first
real test data point arrives (see
mite/cli/influxdb.py).
Testing
pytest test/test_influxdb_exporter.py
test/test_influxdb_exporter.py
covers InfluxCounter, InfluxGauge and InfluxHistogram point conversion,
delta/cumulative field correctness, and histogram percentile math. These tests
exercise the stat model directly and do not require a running InfluxDB instance
or network access (no backend is constructed).
Architecture
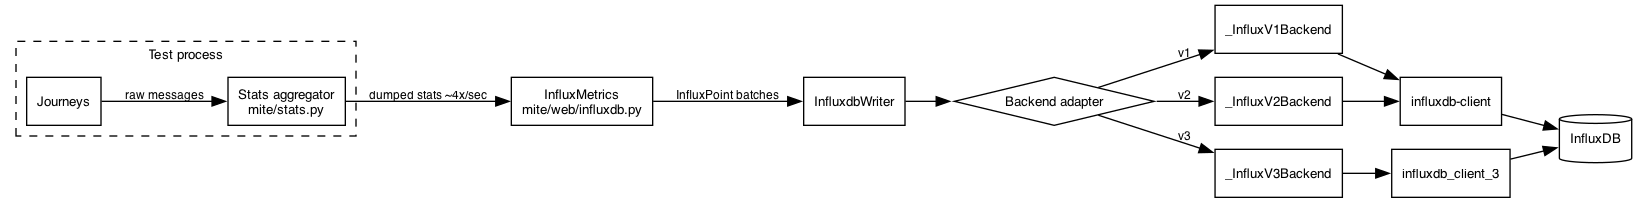
Files:
mite/web/influxdb.py — core writer, stat aggregation/point conversion, and backend adapters
mite/web/__init__.py — Flask app exposing
/metrics(Prometheus); also re-exportsInfluxMetricsmite/web/prometheus.py — sibling Prometheus exporter (not covered here)
Layers
Stat model (
InfluxStat,InfluxCounter,InfluxGauge,InfluxHistogram) Mirror the shape ofmite.statstypes but render toInfluxPointobjects instead of Prometheus text. Each keeps running totals plus a_prev_*snapshot so thatto_points()can emit both a delta (value,count,sum, percentiles computed from the delta buckets) and a cumulative value (value_cumulative,count_cumulative, …) per flush.InfluxHistogramadditionally reconstructs percentiles from histogram buckets (_percentile_from_buckets) and can optionally emit raw bucket points (include_buckets=True, Prometheus-styleletag) for exact reconstruction downstream.InfluxMetrics(extendsInfluxdbWriter) The stats sink.process(message)is called with a stats dump (a list of per-metric dicts produced bymite.stats.Stats). It creates/updates the relevantInfluxStatinstances, buffers the resulting points, and flushes them to InfluxDB at a throttled cadence:MIN_FLUSH_INTERVAL = 1.0s— stats dumps arrive roughly every 0.25s but a single Influx write can take longer, so points are buffered across severalprocess()calls and flushed at a slower, steadier cadence.MAX_PENDING_POINTS = 5000— hard cap on buffered points; oldest points are dropped (with an error log) if a stalled backend can’t keep up, to bound memory on long-running tests.A batch is only cleared from the pending buffer once
write_points()actually accepted it (i.e. the write wasn’t skipped) — otherwise a busy writer would silently lose points.
InfluxdbWriterThe transport layer, independent of the stats model. Responsibilities:Instantiates the correct backend adapter via
_create_influx_backend.Writes are asynchronous: a single-worker
ThreadPoolExecutorplus aBoundedSemaphore(1)ensure at most one write is ever in flight. If a new batch of points arrives while a write is still pending,write_points()returnsNoneimmediately rather than blocking or queuing — i.e. writes are fire-and-forget and a slow backend causes batches to be skipped (and merged into the next flush byInfluxMetrics), never backpressure on the caller.Skip accounting: logs a
WARNINGper skip, escalating toERRORonceCONSECUTIVE_SKIP_ALERT_THRESHOLD(50) consecutive skips occur, and every multiple thereof, so a backend that’s permanently falling behind is visible without flooding logs under normal load spikes.close()shuts down the executor (waiting for any in-flight write) and closes the underlying client.
Backend adapters (
_InfluxBackendABC) All adapters implementwrite_points(points: list[InfluxPoint])andclose(), isolating the rest of the system from version-specific client APIs:_InfluxV2ClientBackend— base class wrappinginfluxdb_client.InfluxDBClientwithSYNCHRONOUSwrites (used directly for v2)._InfluxV1Backend— subclasses the v2 client backend, mapping the legacydatabase/retention_policy/username:passwordmodel onto the v2 client’sbucket/tokenmodel (InfluxDB 1.8+ compatibility API)._InfluxV2Backend— thin config wrapper around_InfluxV2ClientBackend._InfluxV3Backend— uses the separateinfluxdb_client_3package (InfluxDBClient3), InfluxDB’s v3/IOx line.Client imports are deferred (done inside
__init__/write_points) so only the SDK needed for the configured version has to be installed.
The version to use is selected via
_create_influx_backend/_create_single_backend, which readsINFLUXDB_VERSION(viapackaging.version.Version, so values like1,2.0,v3all parse — only the major version is used) and dispatches to the matching adapter, defaulting to v3 if unset.
Multi-instance support
Every config lookup and class constructor accepts a suffix (e.g. "",
"_2", "_3", …), allowing simultaneous writes to N independent InfluxDB
instances from a single test run — e.g. INFLUXDB_HOST and
INFLUXDB_HOST_2 configure two different destinations. The --influxdb=N
CLI flag controls how many InfluxdbWriter/InfluxDBProcessor instances are
created, each with its own suffix.
Distributed topology
Configuration reference
Selected once via INFLUXDB_VERSION{suffix} (default "v3"; only the major
version matters: 1, 2, 3). Remaining variables depend on the version:
Version |
Required env vars |
Notes |
|---|---|---|
v1 |
|
|
v2 |
|
Uses |
v3 |
|
Uses |
For a second simultaneous instance, suffix every variable with _2
(INFLUXDB_VERSION_2, INFLUXDB_HOST_2, …), _3 for a third, etc.
Missing required variables raise InfluxConfigError
(mite/exceptions.py)
and abort writer creation.
Key classes reference
Class |
Role |
|---|---|
|
Plain dataclass: |
|
Convert |
|
Async, single-in-flight-write transport to a configured backend |
|
|
|
Version-specific client adapters |
|
Message processor wiring a |